Experiment 5 · MinAtar Breakout
Can a language model write a useful neural network?
We tested whether language models could produce the numerical weights for a small game-playing network directly, without training feedback.
The networks controlled Breakout in MinAtar. Their scores were measured over thousands of episodes, then checked against the preserved experiment files and raw evaluation data.
10 × 10 game board
From text to play
How the experiment works
- 1
Give the task
The prompt describes Breakout, the network, and the weight format.
- 2
Generate weights
A model returns numerical values for the network’s connections.
- 3
Run the policy
The fixed network chooses actions from the board it observes.
- 4
Measure performance
Thousands of episodes show how many bricks each policy breaks.
Corrected local evaluation
Mean score by condition
Research data are loading.
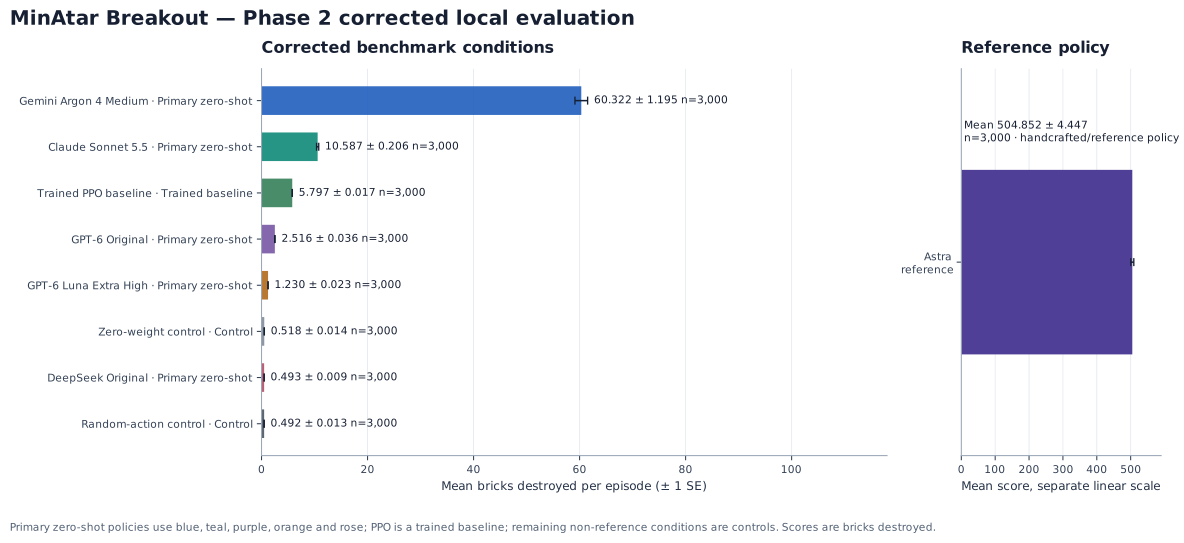
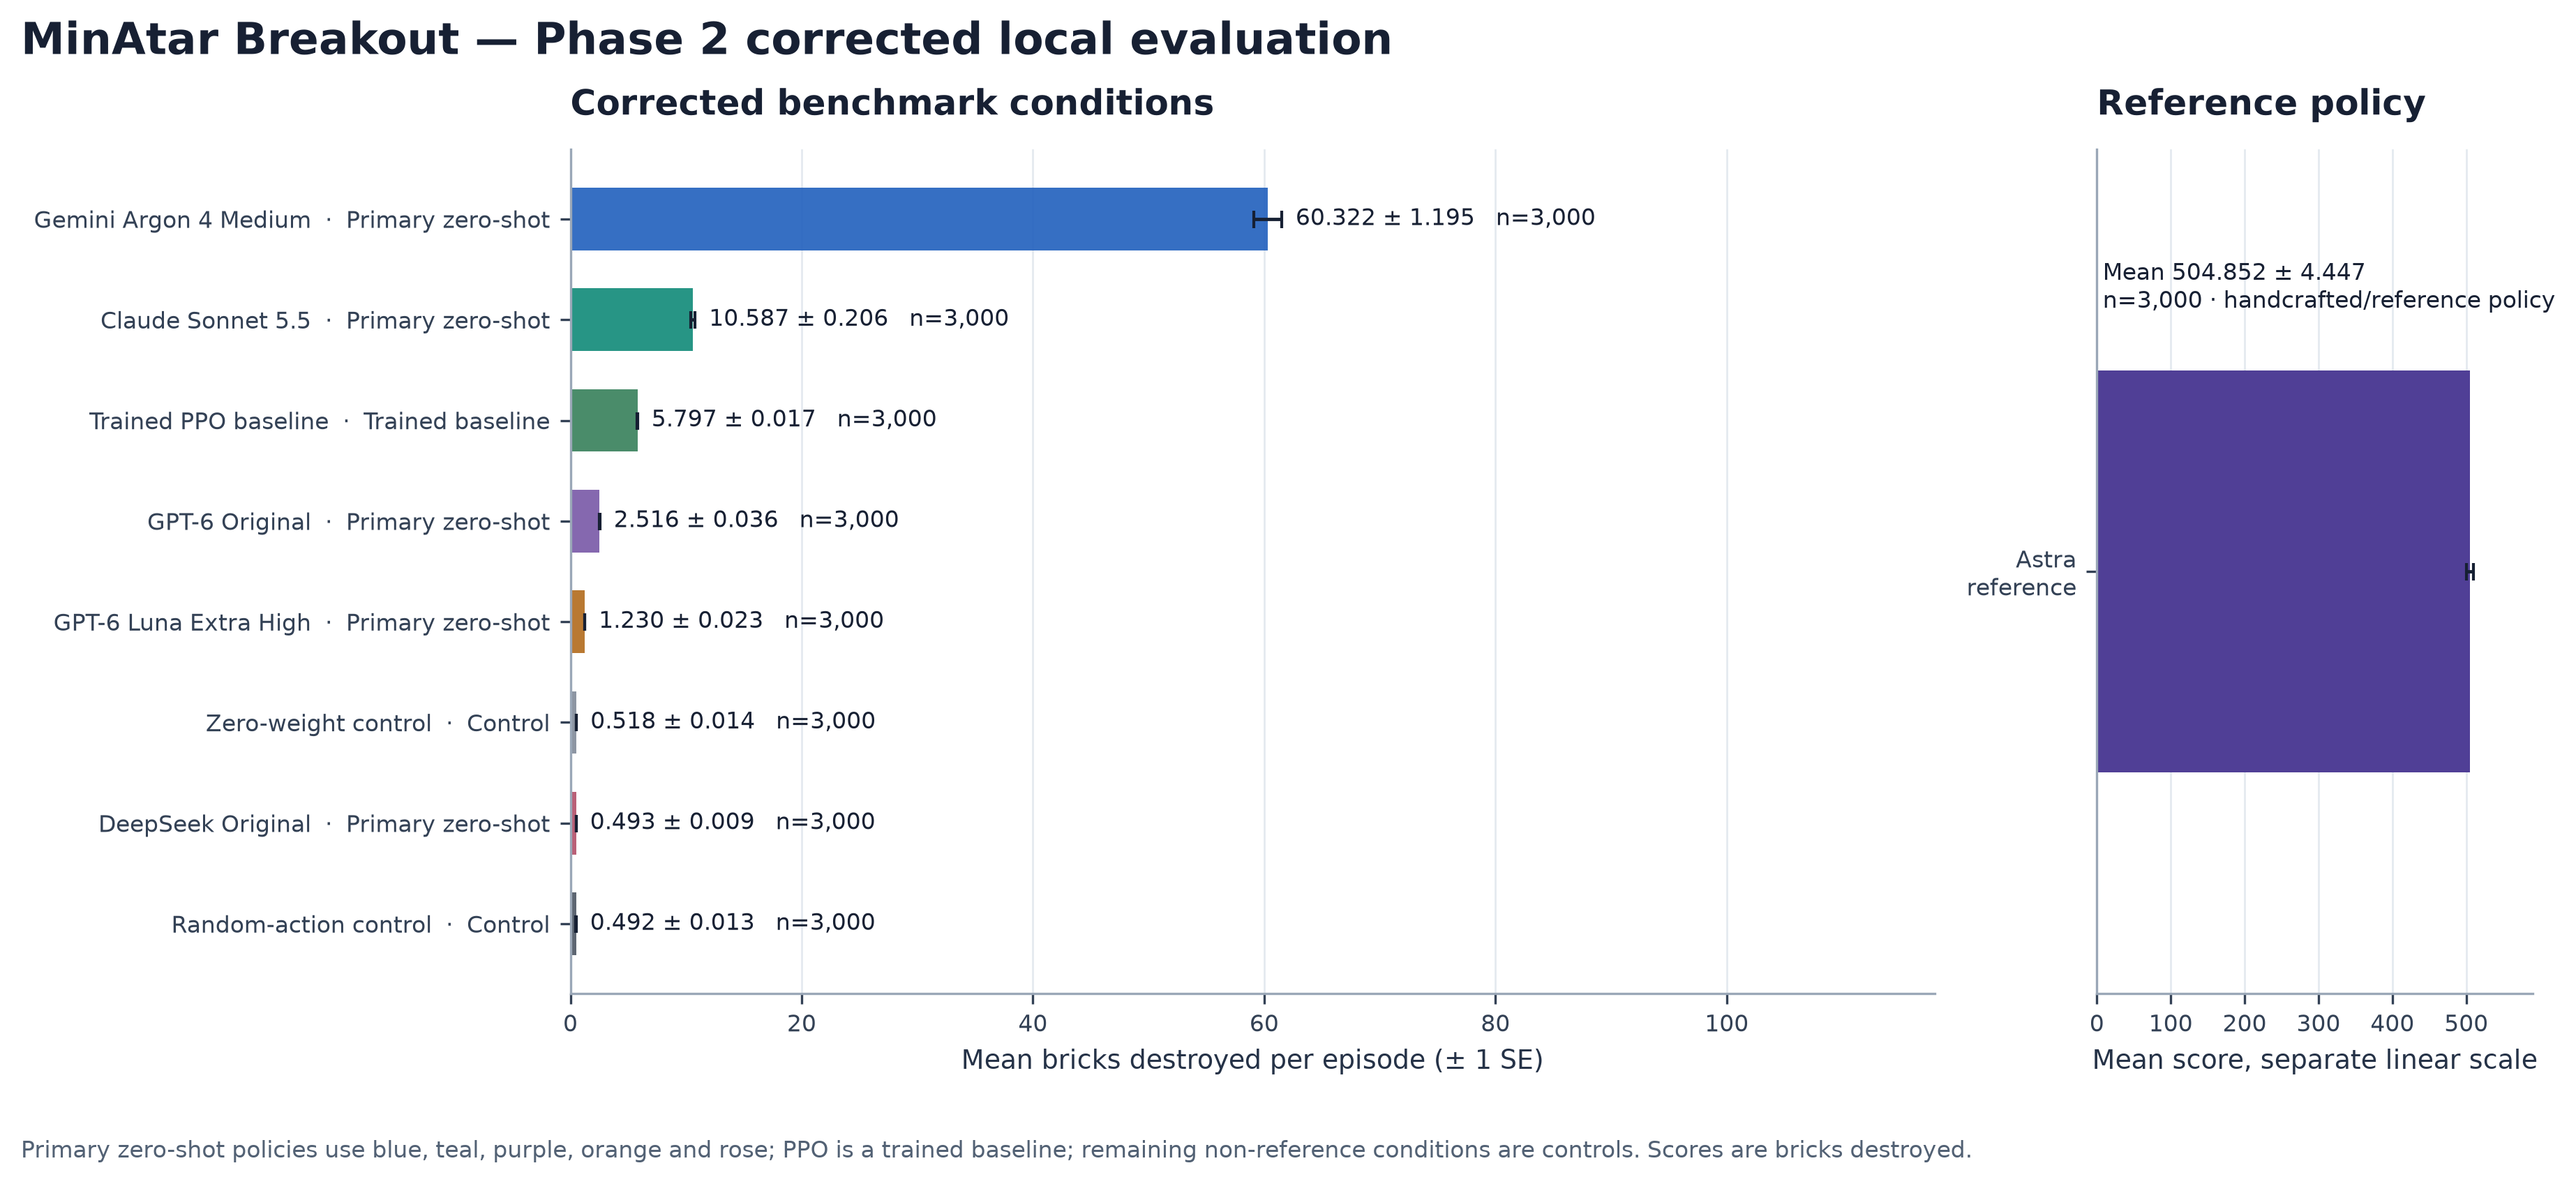
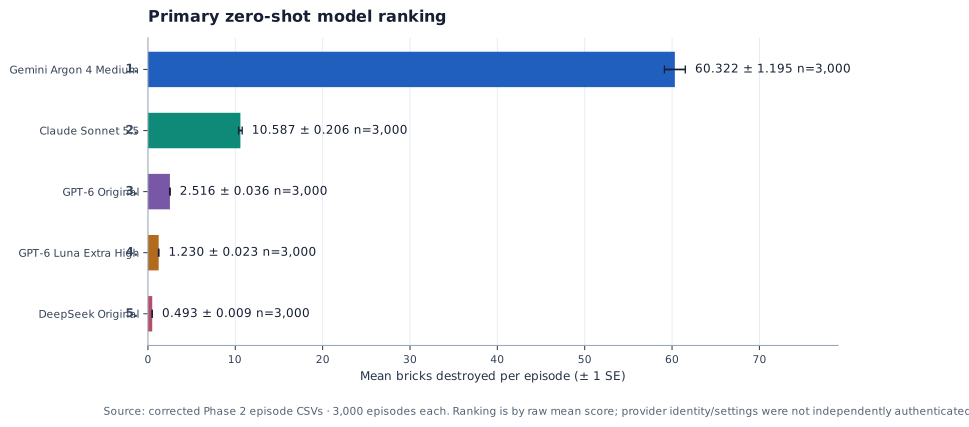
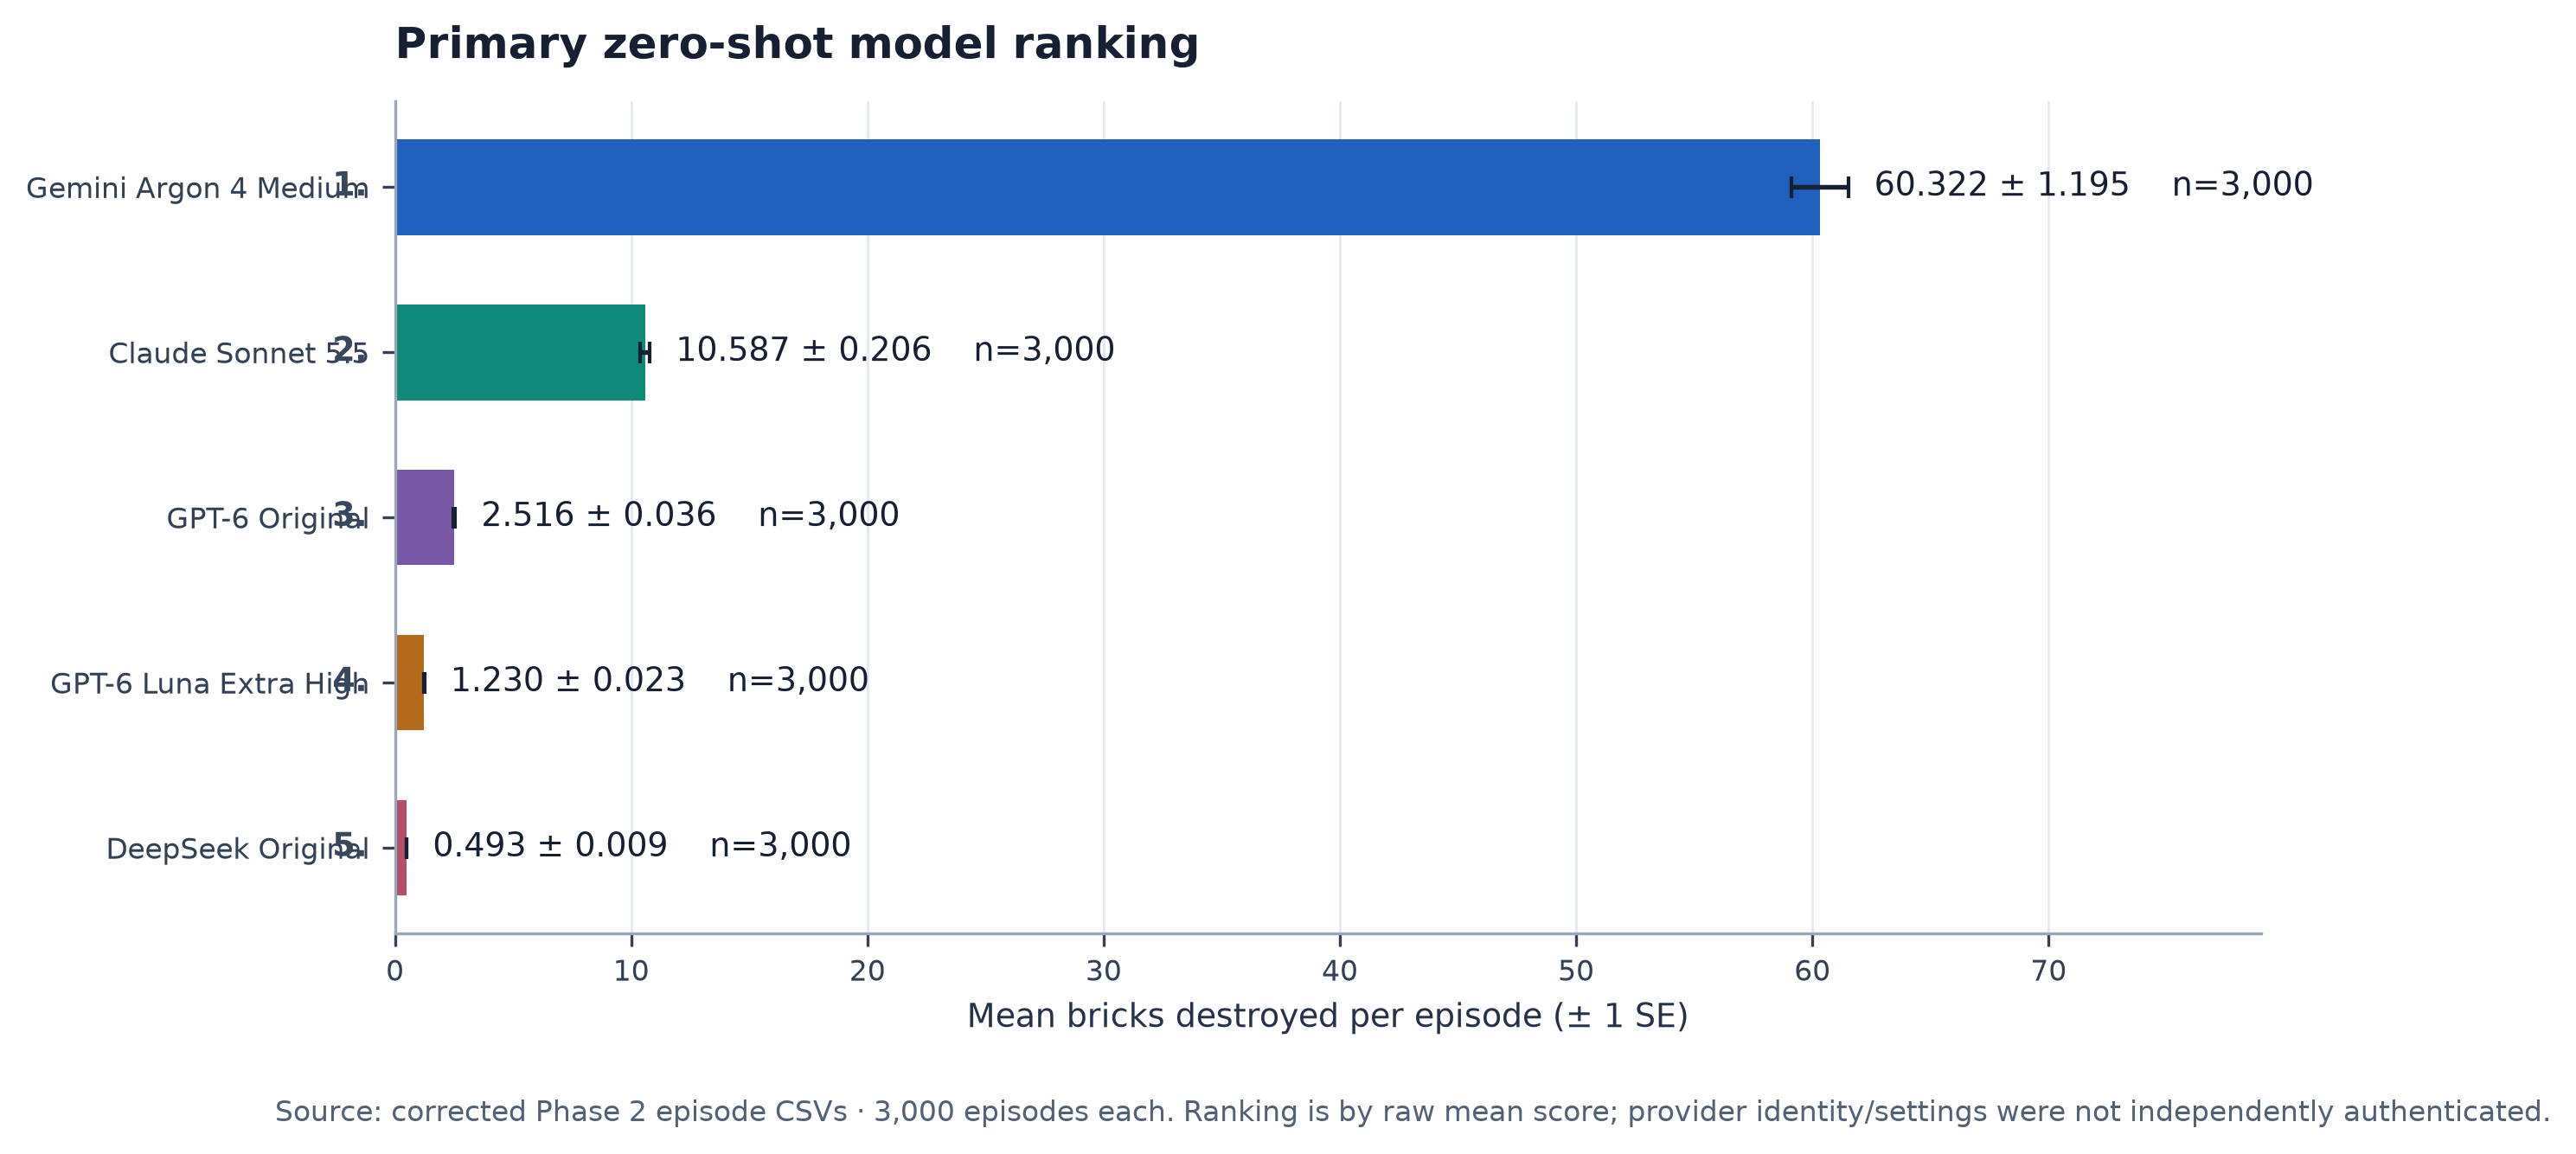
The Astra reference and trained PPO baseline are shown in separate categories from the five zero-shot model generations.
Separate experiment
Argon High — iterative development
Two researcher-directed follow-ups were evaluated as separate versions. Their results are not part of the original five-model zero-shot ranking.
Browser demonstration
Live Arena
Watch one fixed network play a browser implementation of MinAtar Breakout. The seed makes this demo repeatable in this browser; it does not reproduce the evaluation’s NumPy random streams.
The game uses the 10 × 10 MinAtar board and one-cell paddle.
Current network input
Observation
Each cell maps one board position and one input channel. The network receives all six channels flattened into 600 values.
Network decision inspector Closed by default
The network turns the 600 binary inputs into hidden activations and six action scores (logits). Softmax converts those scores into action probabilities. This describes the computation; it does not assign a causal meaning to individual neurons.
Reset or step the arena to inspect a decision.
This demonstration episode
Episode summary
Five original zero-shot generations
Models
Each profile describes the recorded generation condition and the exact weight archive evaluated. The project records model labels and some settings locally; the audit did not independently authenticate them with provider records.
Primary zero-shot conditions
One archived generation per recorded model condition.
Model records are loading.
Separate iterative-development experiment
Gemini Argon High — three development stages
Original supplied assignments and two researcher-directed follow-ups, preserved and evaluated as distinct artifacts.
Iterative-development records are loading.
The first stage is the inline v1 assignment excerpt. Each follow-up is a separate supplied script and weight archive. Attribution to Gemini Argon High is recorded from the user's description; provider identity and the complete original provider response are not independently authenticated. The repository's other archived Gemini run is a separate artifact.
Separate post-hoc work
DeepSeek Corrected
This is a researcher-modified intervention created after the original DeepSeek response. It is not an original zero-shot generation and is excluded from the five-model ranking.
Reference, trained baseline, and controls
These conditions are useful comparisons, not extra zero-shot model generations.
Phase 2 corrected evaluation
Results
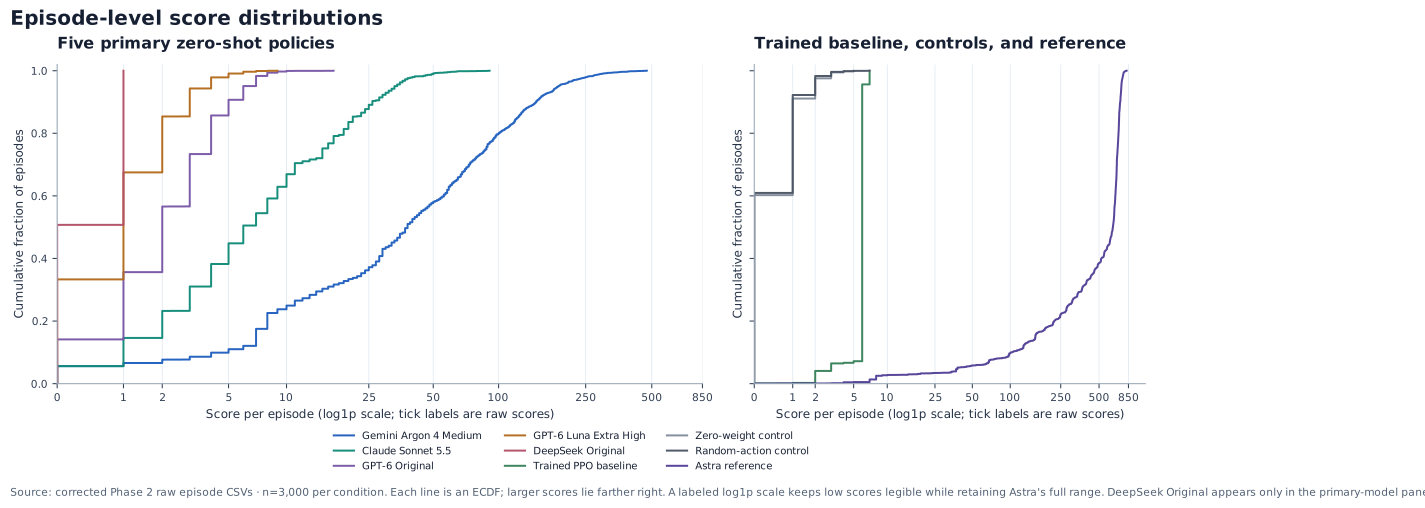
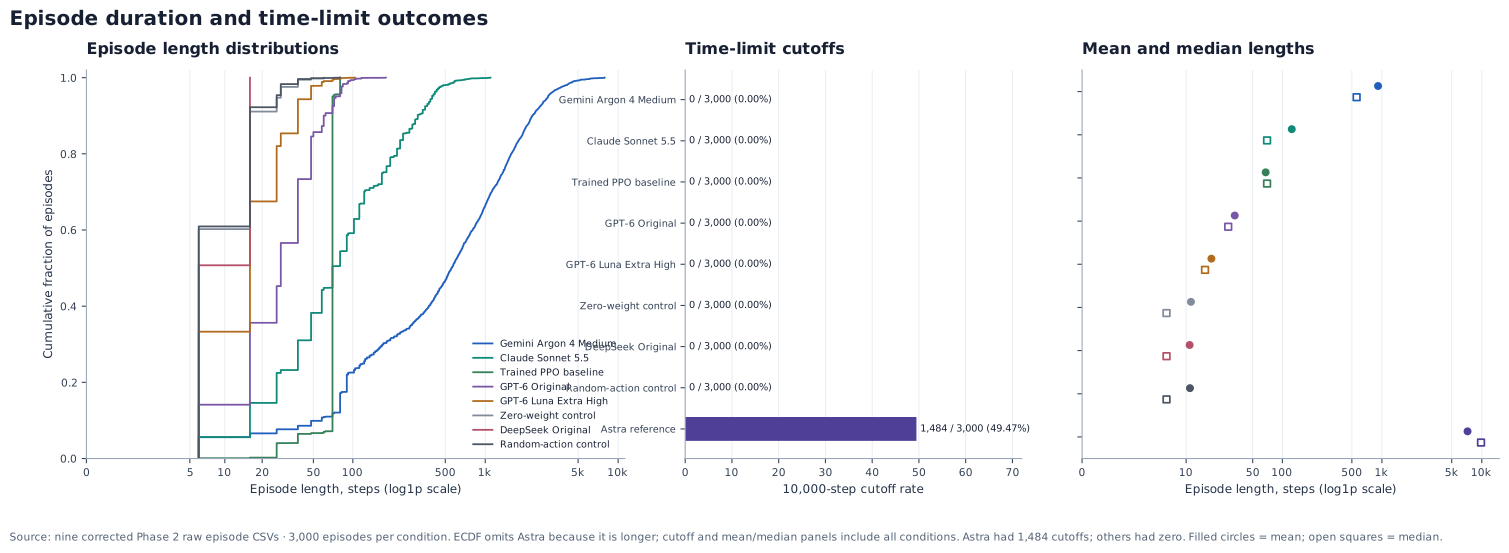
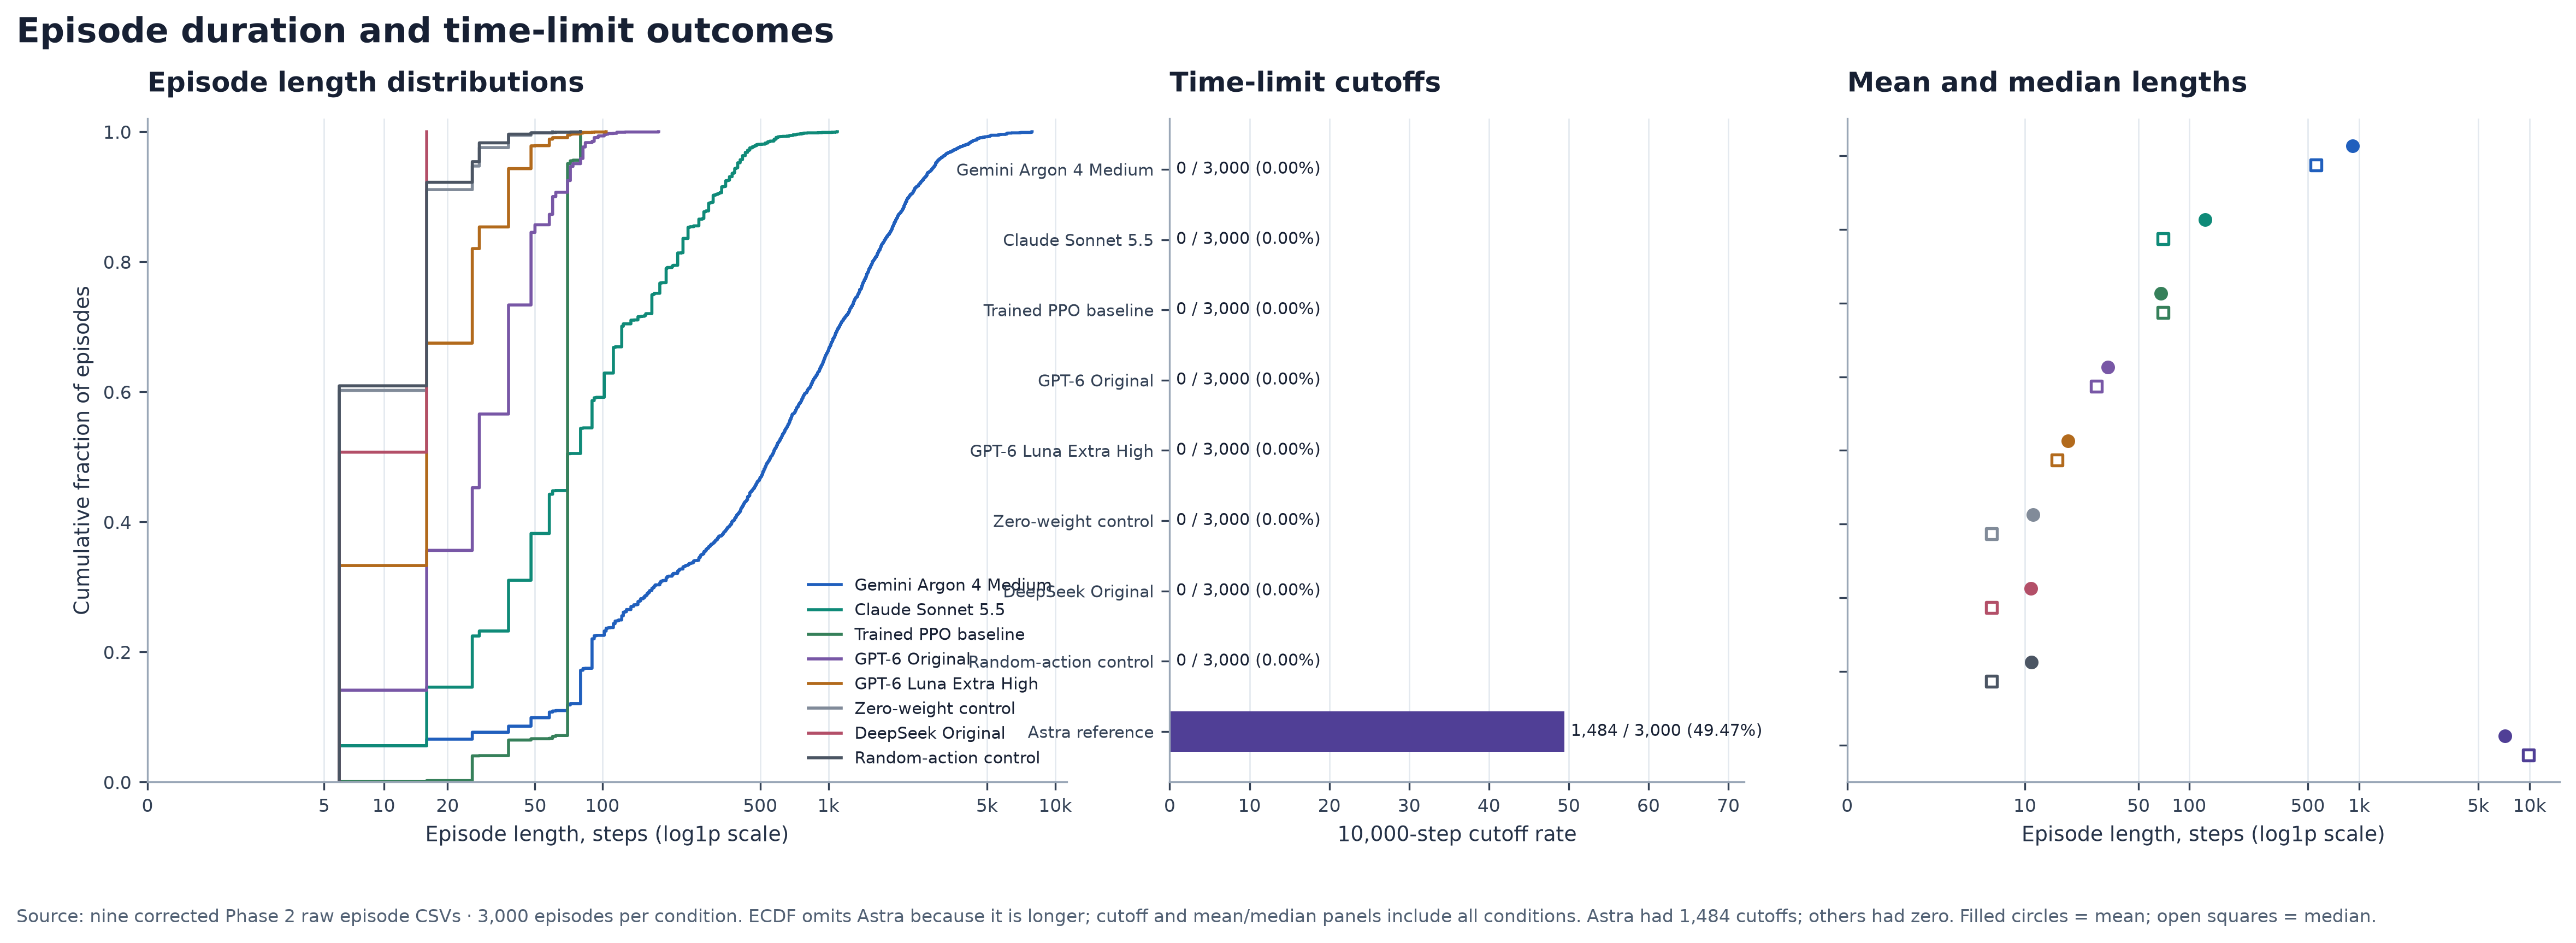
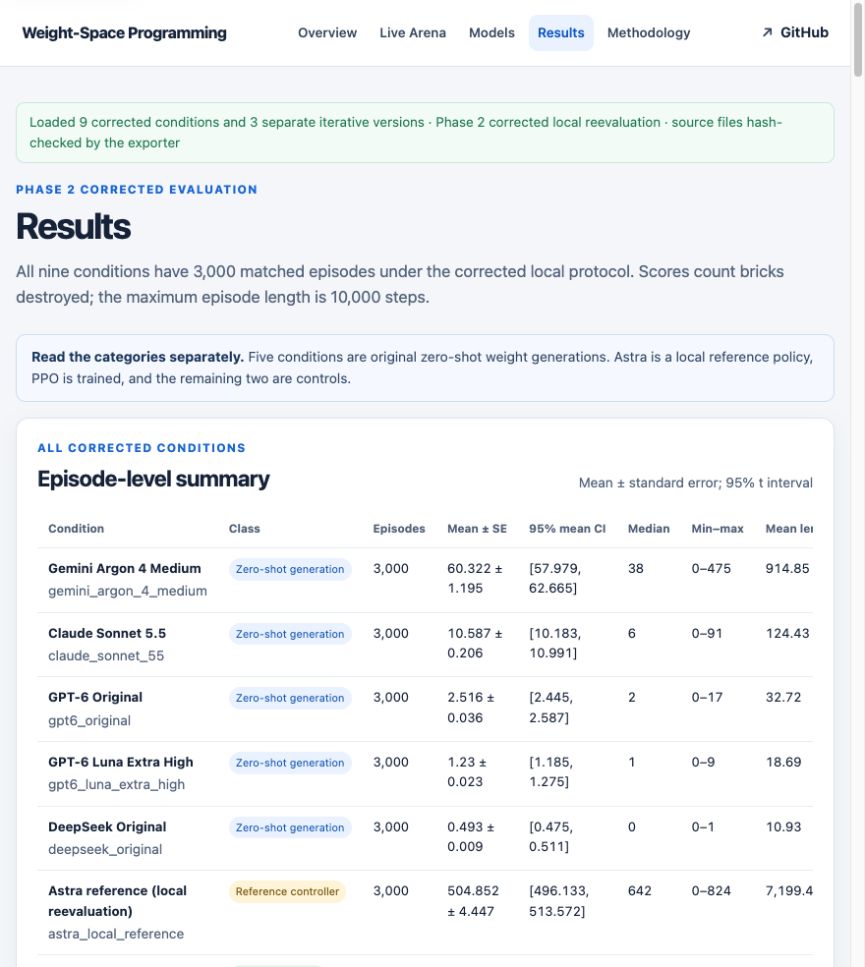
All nine conditions have 3,000 matched episodes under the corrected local protocol. Scores count bricks destroyed; the maximum episode length is 10,000 steps.
All corrected conditions
Episode-level summary
| Condition | Class | Episodes | Mean ± SE | 95% mean CI | Median | Min–max | Mean length | Median length | 10,000-step cutoffs | Data |
|---|
The mean is the average score. Standard error and the 95% t interval describe uncertainty in that average; they are not the range of individual episode scores. The median is the middle score when episodes are ordered.
Distribution
Episode scores
Mean score
Category-aware comparison
Bars share a linear score scale. The reference is much higher than the zero-shot model results, so inspect the numeric labels and uncertainty in the table.
What policies did
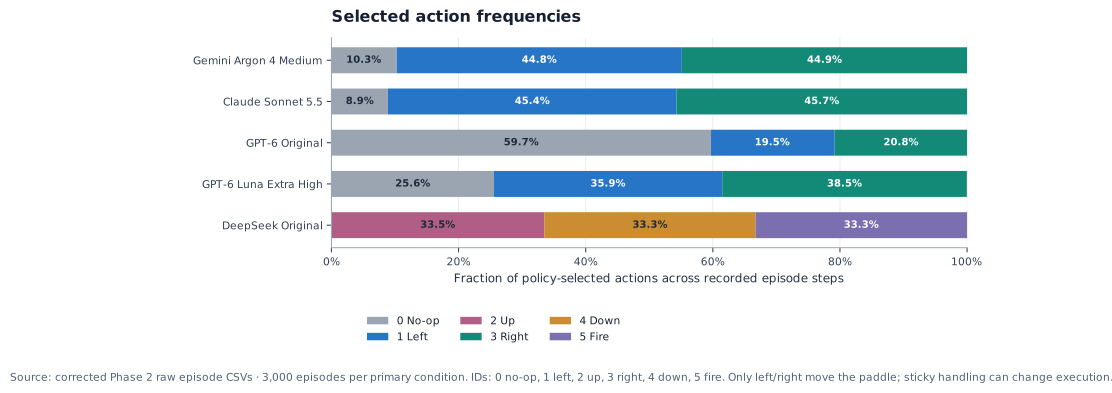
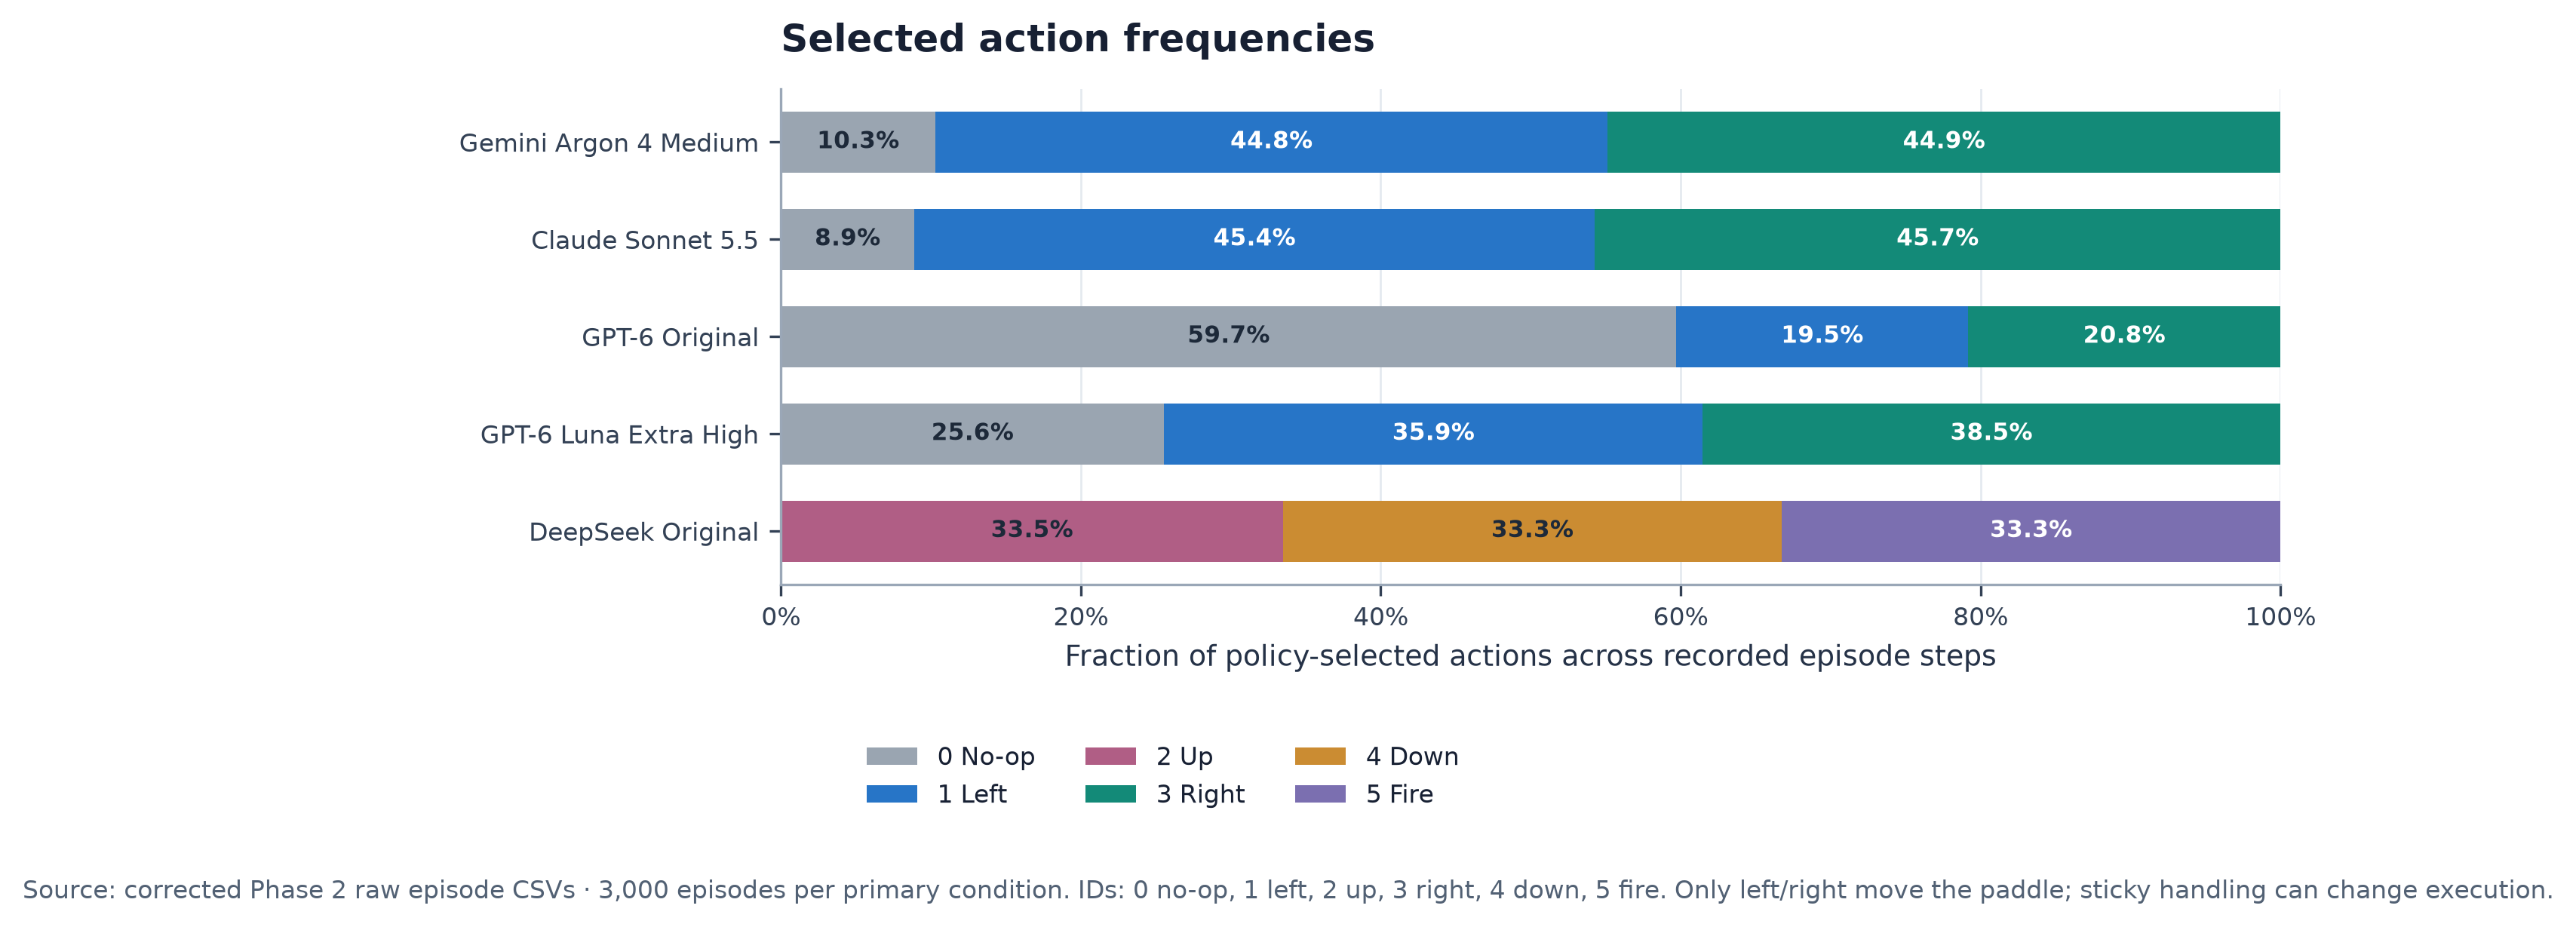
Selected action counts
These are actions proposed by the policy. Sticky-action handling may cause MinAtar to execute the previous action instead.
Matched episodes
Statistical comparisons
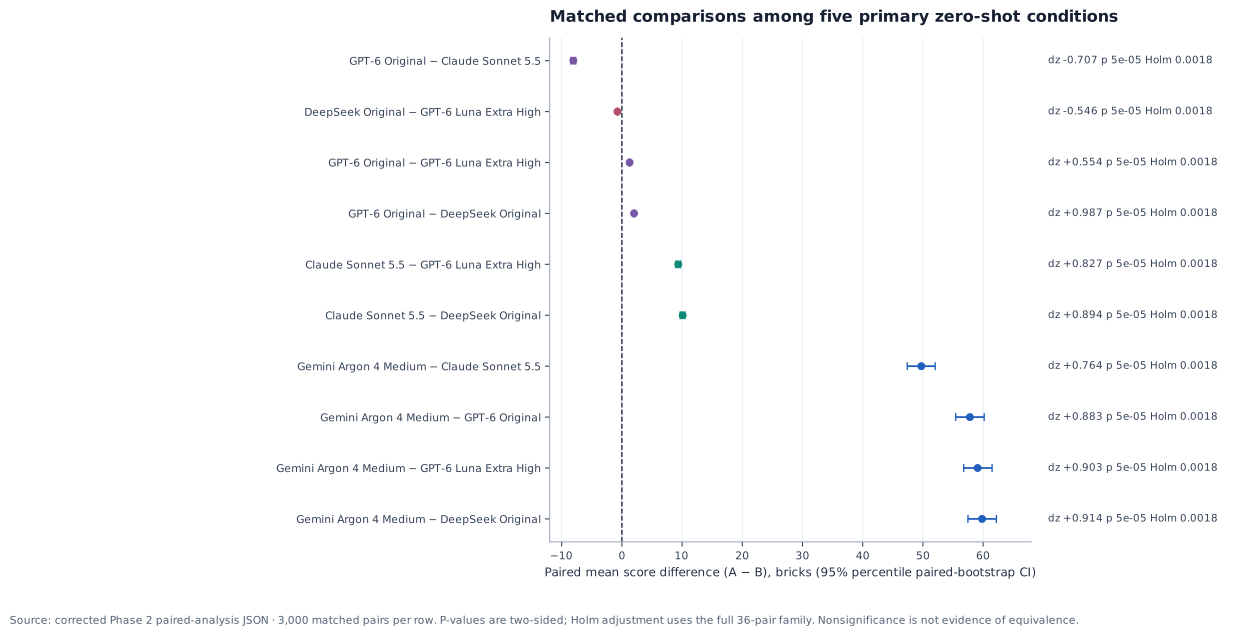
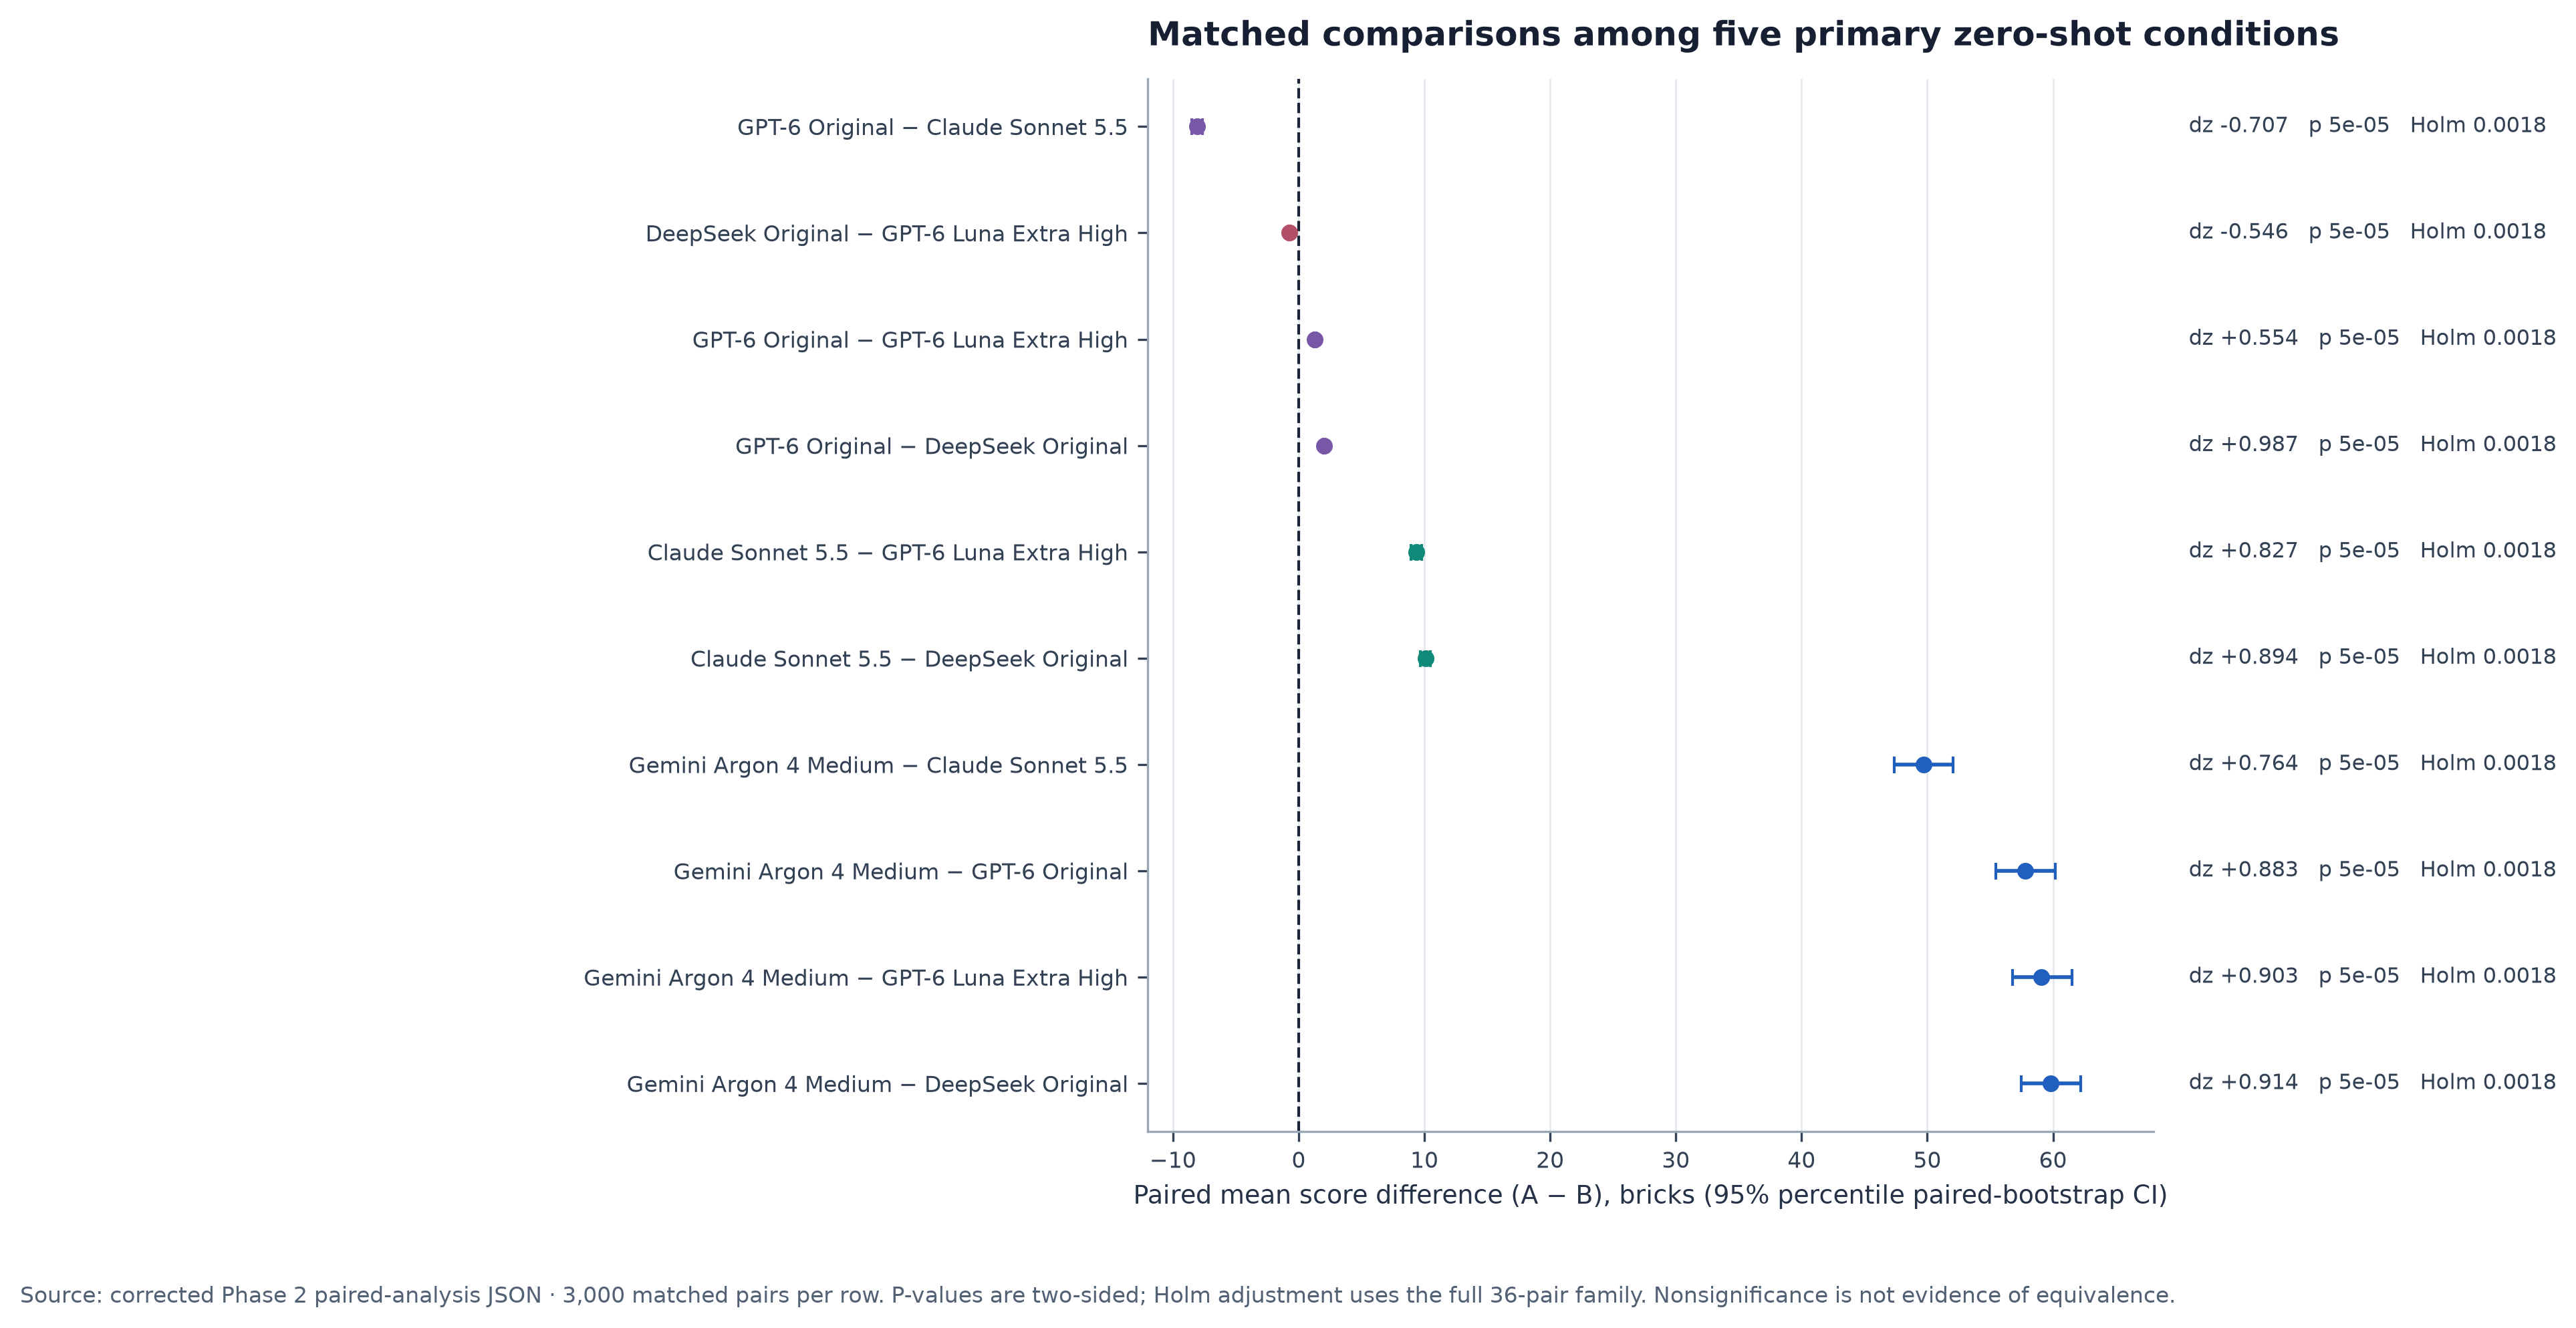
Each comparison subtracts scores from episodes with the same base seed. The bootstrap interval shows uncertainty by resampling those matched pairs. The two-sided sign-flip test checks whether paired differences are centered around zero. Cohen’s dz scales the average difference by the spread of paired differences. The p-value indicates how unusual the result would be under no average difference; smaller values are less compatible with that assumption. Holm correction adjusts the 36 p-values to limit false positives across the full set. A nonsignificant result is not evidence of equivalence.
| Condition A − B | Mean difference | 95% paired bootstrap CI | Cohen’s dz | Two-sided p | Holm p |
|---|
Different protocol category
Argon High — iterative development
These three versions are not directly interchangeable with original zero-shot conditions: each follow-up was a researcher-directed change after the preceding output.
Loading the iterative source-record integrity note.
Mean score ± SE
Three separate versions
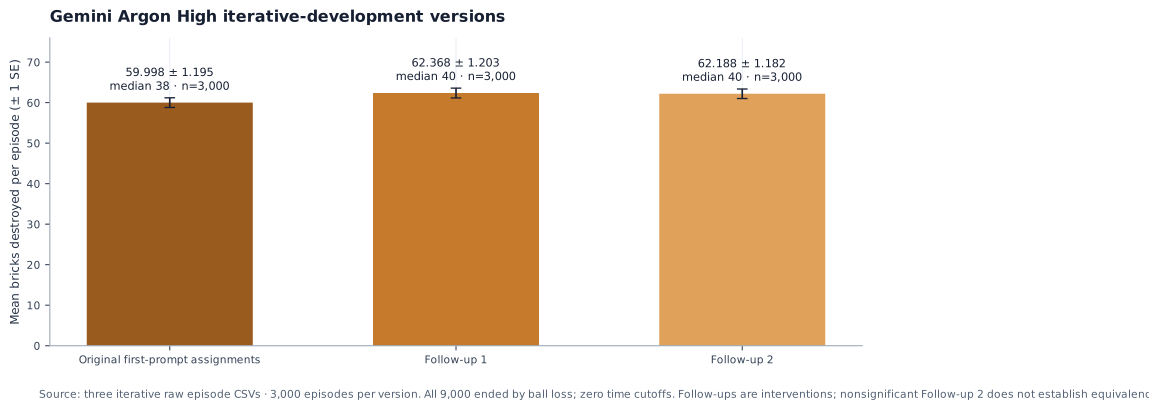
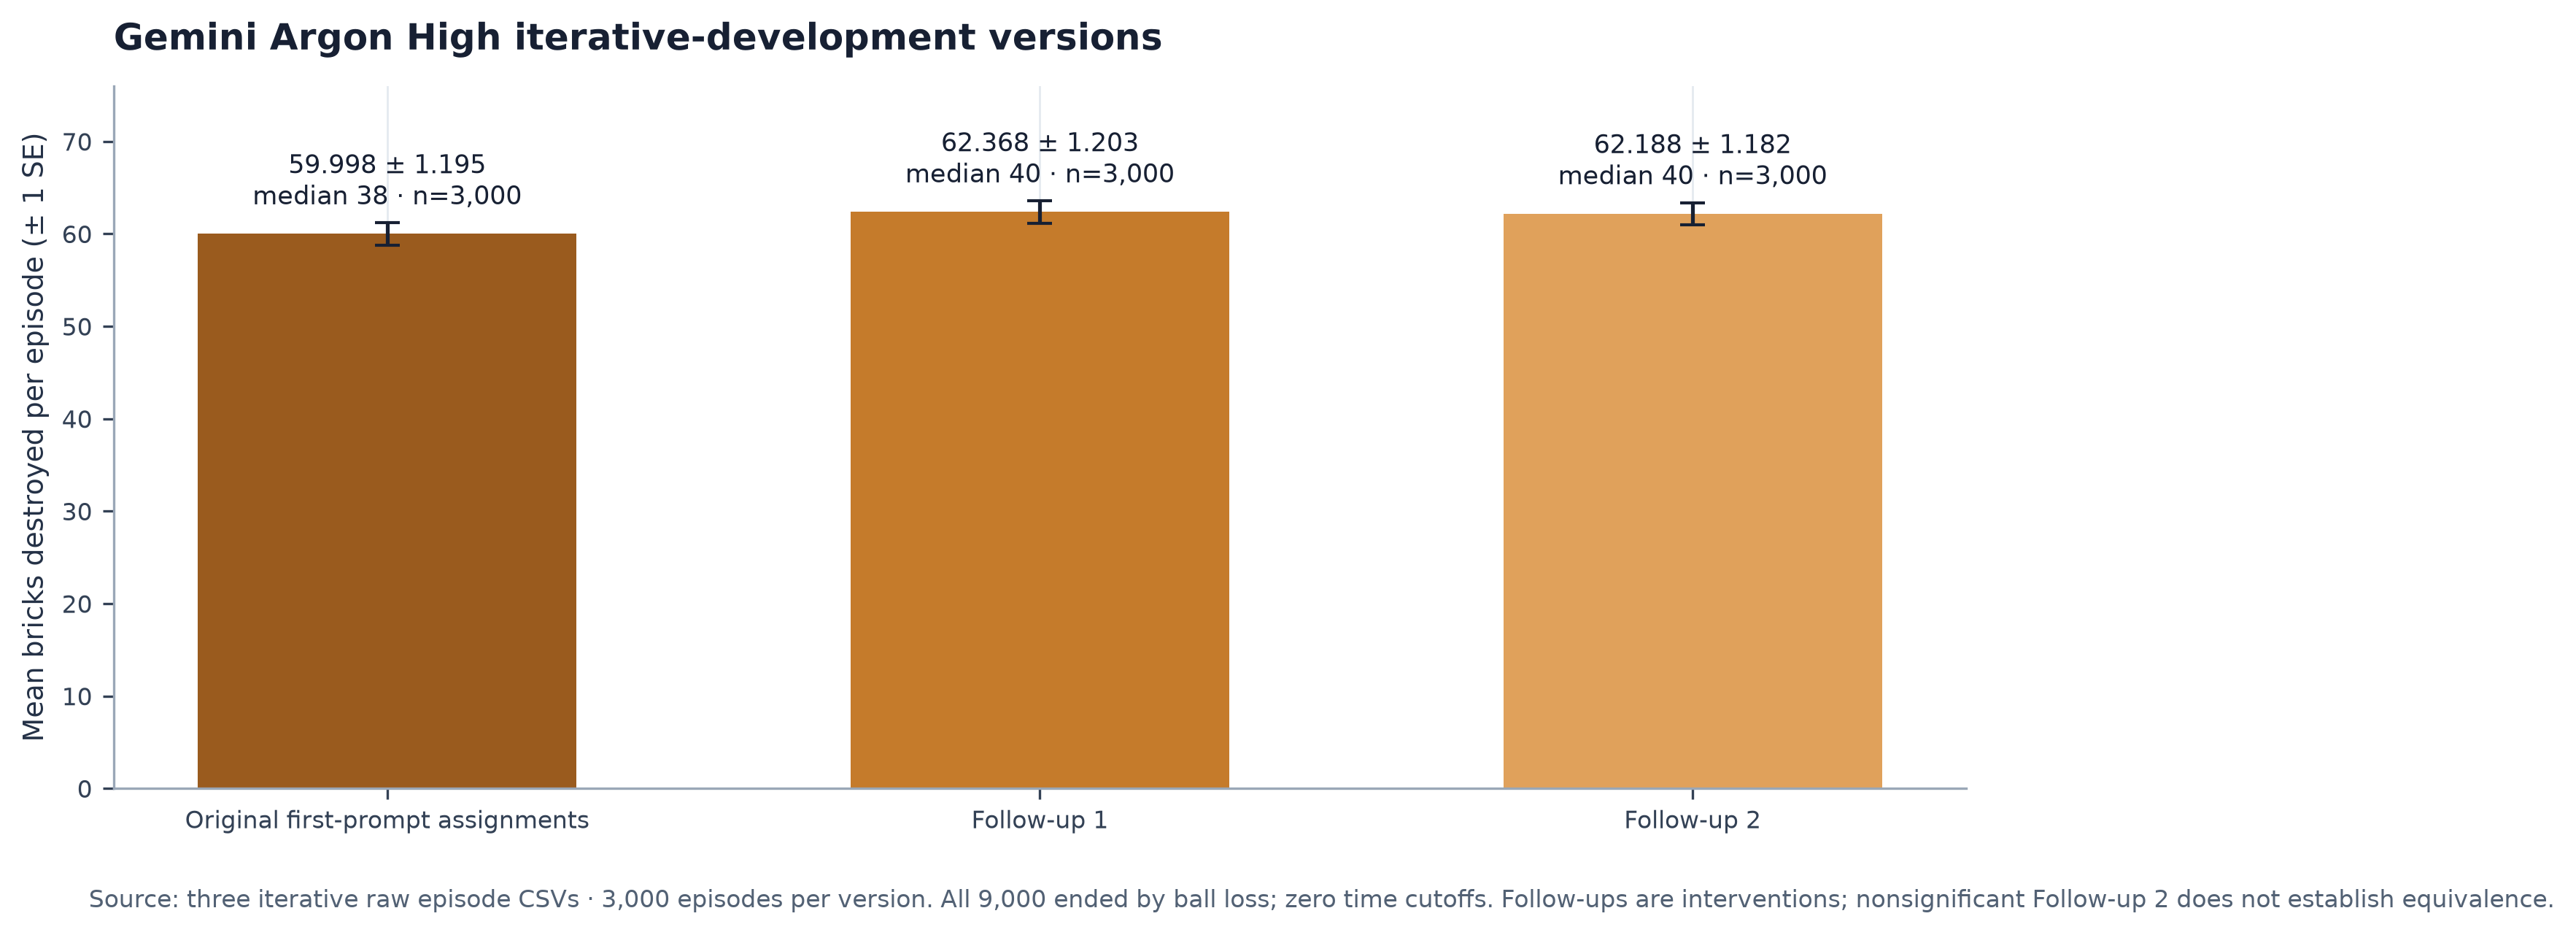
Bars show mean score; the numeric labels show mean ± standard error. The episodes are paired by seed identifiers.
Episode score distributions
Score ranges by version
Each row is a 20-bin histogram from that version's raw episode CSV; all rows use the same 0-to-maximum score scale.
Full-run summaries
Episode-level results
| Version | Episodes | Mean ± SE | Median | Min–max | Ball loss | 10,000-step cutoffs | Data |
|---|
All 9,000 episodes ended by ball loss. There were no time-limit cutoffs. Mean score is bricks destroyed; standard error describes uncertainty in the average, not the spread of individual scores.
Matched episode comparisons
Paired differences and effect sizes
Loading paired difference interpretation.
Differences are condition A minus condition B, paired by seed group and episode index. Confidence intervals use the project's paired bootstrap; p-values are two-sided sign-flip tests with Holm correction over these three comparisons. A nonsignificant result does not establish equivalence.
| A − B | Mean paired difference | 95% bootstrap CI | Cohen's dz | Two-sided p | Holm p |
|---|
Provenance and validation limits
What the preserved evidence says
- The original is a user-supplied inline assignment excerpt; the exact original provider response, provider identity, and generation settings remain unauthenticated.
- The separate archived Gemini run was not substituted for these versions. Its recorded metadata conflicts with the Phase 2 Argon 4 Medium label.
- The supplied Follow-up 2 verifier fails at a float64 assertion that requires a probability to exceed 1.0. Its source is preserved unchanged. A separate comparison against its own oracle found no action mismatches across 7,280 enumerated states; that does not prove the oracle captures every game behavior.
- The experiment report records 77 relevant project tests passing, while explicitly excluding GUI validation. The graphical-interface test failures remain a separate unresolved Phase 3 limitation.
Protocol comparison
Corrected versus historical evaluation
These are descriptive changes across two evaluation protocols. Different environment and policy draws changed with the separated-stream protocol, so the change cannot be attributed to RNG separation alone.
| Condition | Matched episodes | Mean change | 95% paired bootstrap CI |
|---|
Figures from raw records
Visual Results & Gameplay
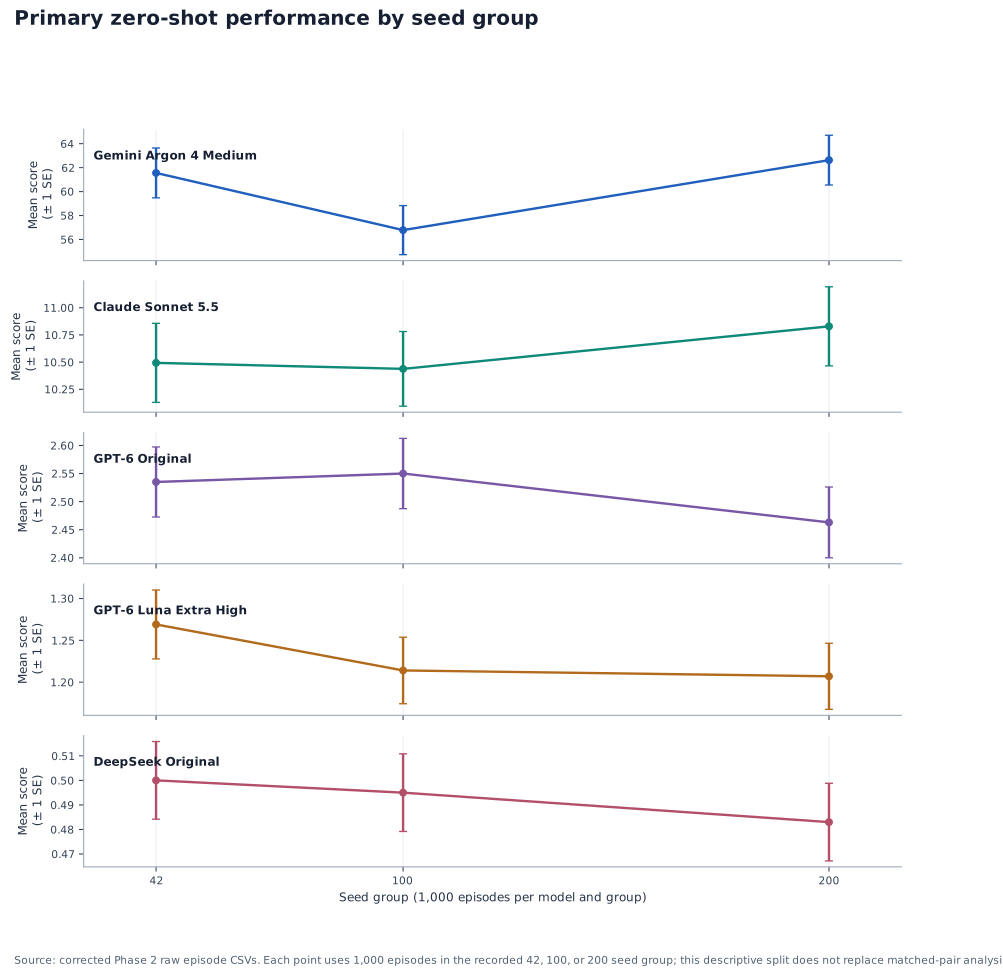
These publication-style figures are regenerated from the preserved episode CSVs and checked analysis outputs. Phase 2 benchmark results and the separate iterative-development experiment are shown in different groups.
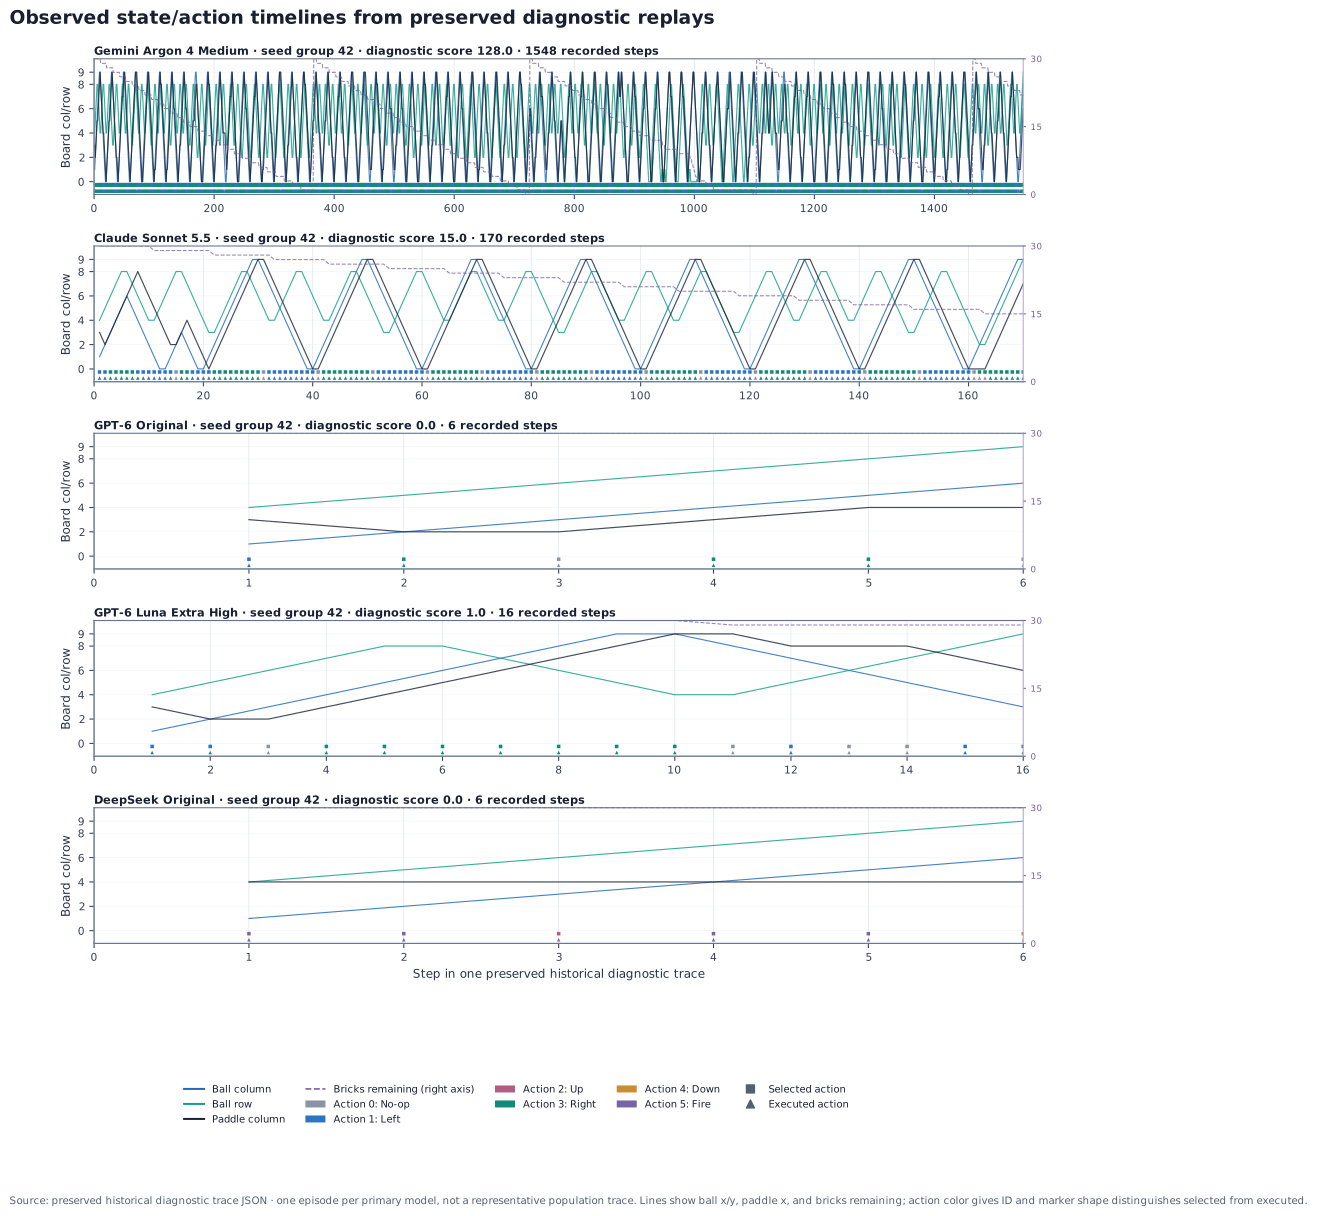
Live policy demonstration
Gameplay recordings and Arena captures
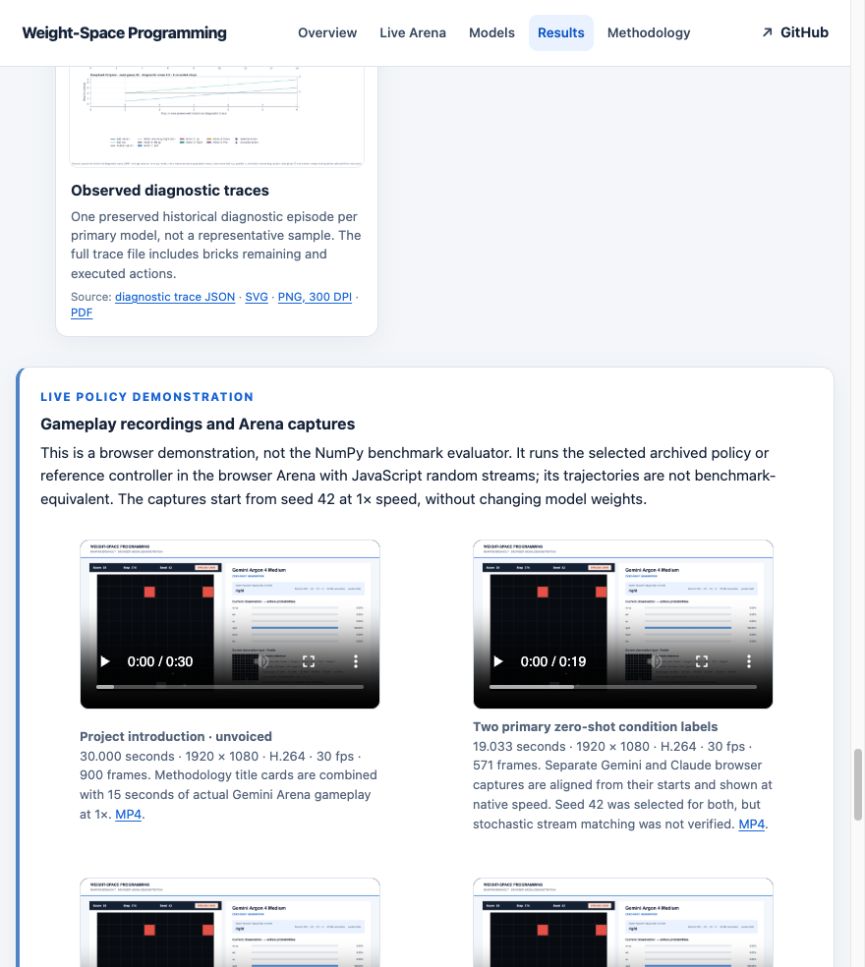
This is a browser demonstration, not the NumPy benchmark evaluator. It runs the selected archived policy or reference controller in the browser Arena with JavaScript random streams; its trajectories are not benchmark-equivalent. The captures start from seed 42 at 1× speed, without changing model weights.
30.000 seconds · 1920 × 1080 · H.264 · 30 fps · 900 frames. Methodology title cards are combined with 15 seconds of actual Gemini Arena gameplay at 1×. MP4.
19.033 seconds · 1920 × 1080 · H.264 · 30 fps · 571 frames. Separate Gemini and Claude browser captures are aligned from their starts and shown at native speed. Seed 42 was selected for both, but stochastic stream matching was not verified. MP4.
15.467 seconds · 1920 × 1080 · H.264 · 30 fps · 464 frames. Gemini and Astra are separate browser captures, shown at native speed; stream matching was not verified. Astra is a handcrafted/reference controller, not an LLM-generated policy. MP4.
20.666 seconds · 1920 × 1080 · H.264 · 30 fps · 620 frames. The actual capture shows the live observation, hidden-unit activity counts, output logits and action probabilities, so it also serves as the network-inference demonstration. MP4 · original WebM
19.033 seconds · 1920 × 1080 · H.264 · 30 fps · 571 frames. The shown browser episode ended at score 6 after 70 steps. This one run is illustrative, not a benchmark sample. MP4 · original WebM
15.466 seconds · 1920 × 1080 · H.264 · 30 fps · 464 frames. The clip was stopped during play at score 12, step 133. Astra is not an LLM-generated zero-shot condition. MP4 · original WebM
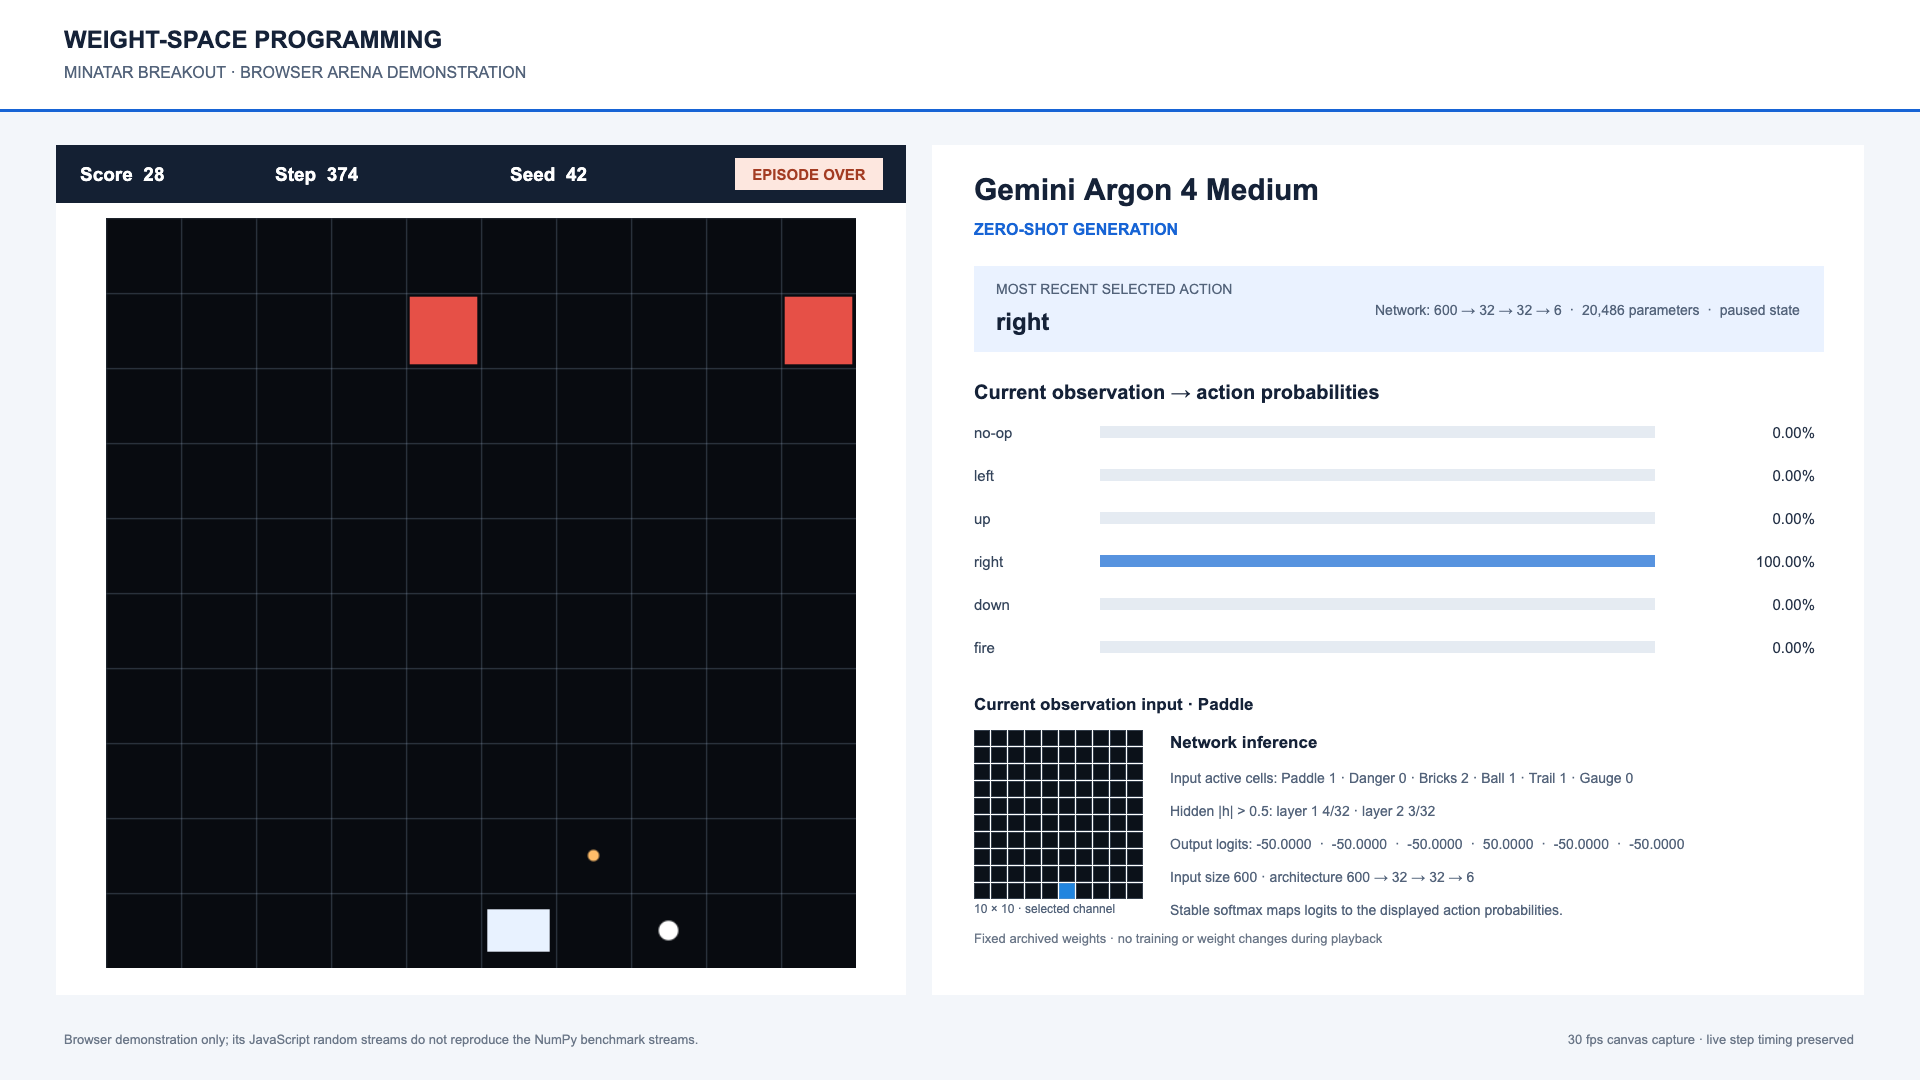
One actual 1920 × 1080 Arena frame. It shows the current observation channel and values produced by the selected policy at that state. Values are from the browser inference path, not a reconstructed illustration.
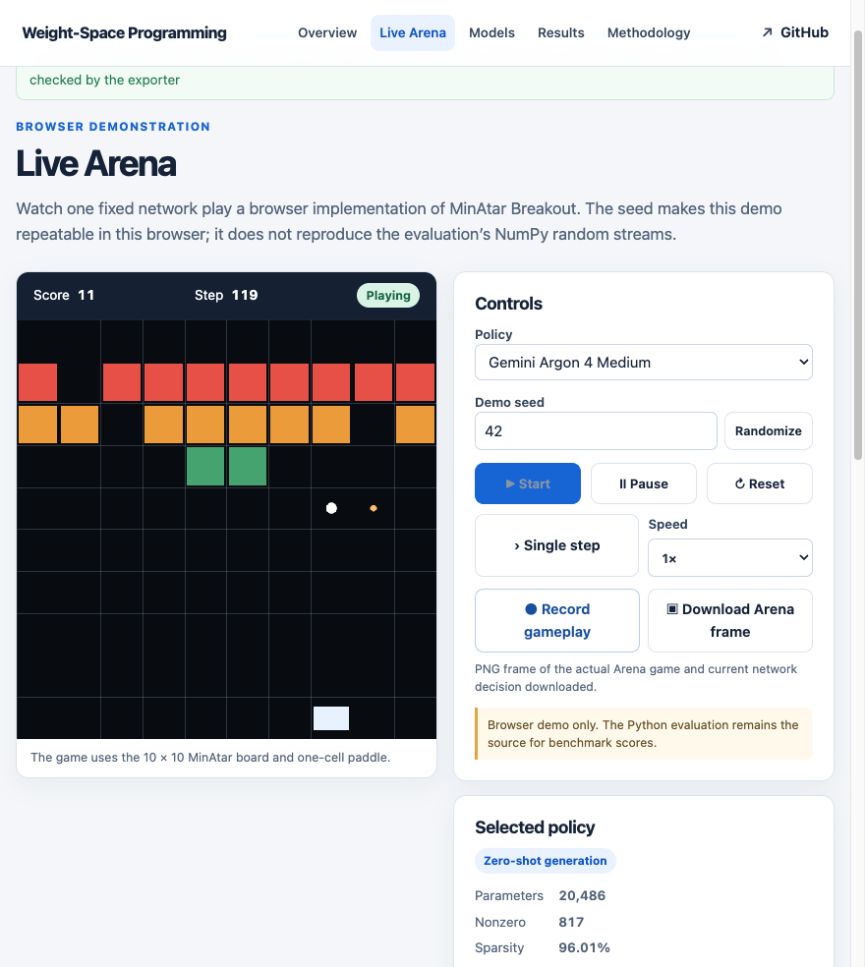
Browser screenshot from active gameplay at score 11, step 119, seed 42. The image shows the actual deployed application interface, not a mockup. Download JPEG.
The two comparisons combine separate 1× recordings selected with seed 42; matching random streams were not verified, and no identical stochastic trajectory is claimed. A separate 30-second, unvoiced introduction uses documented facts and actual captured gameplay. Results-page screenshot · Methodology-page screenshot · Gallery screenshot. File provenance, measured metadata, sizes and hashes are recorded in the gameplay media manifest. Figure source, input hashes and output hashes are recorded in the figure manifest. Capture and media verification instructions.
Download source data
Episode CSVs and analysis bundle
The CSVs below are byte-identical copies of the hash-checked corrected episode files used by the exporter. Source hashes are shown in the model profiles and research JSON.
Download analysis JSONHow it was done
Methodology
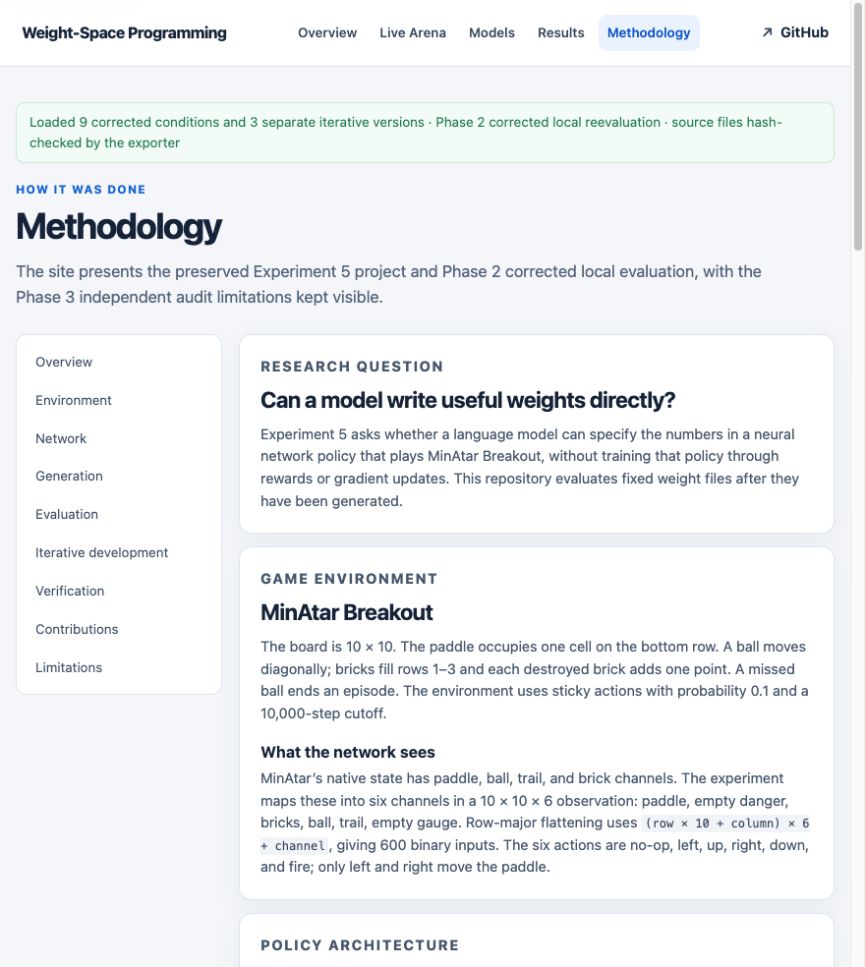
The site presents the preserved Experiment 5 project and Phase 2 corrected local evaluation, with the Phase 3 independent audit limitations kept visible.
Research question
Can a model write useful weights directly?
Experiment 5 asks whether a language model can specify the numbers in a neural network policy that plays MinAtar Breakout, without training that policy through rewards or gradient updates. This repository evaluates fixed weight files after they have been generated.
Game environment
MinAtar Breakout
The board is 10 × 10. The paddle occupies one cell on the bottom row. A ball moves diagonally; bricks fill rows 1–3 and each destroyed brick adds one point. A missed ball ends an episode. The environment uses sticky actions with probability 0.1 and a 10,000-step cutoff.
What the network sees
MinAtar’s native state has paddle, ball, trail, and brick channels. The experiment maps these into six channels in a 10 × 10 × 6 observation: paddle, empty danger, bricks, ball, trail, empty gauge. Row-major flattening uses (row × 10 + column) × 6 + channel, giving 600 binary inputs. The six actions are no-op, left, up, right, down, and fire; only left and right move the paddle.
Policy architecture
600 → 32 → 32 → 6
Each fixed network has two hidden layers with 32 units each. The hidden layers use the tanh function; the final layer outputs six action scores. That is 20,486 parameters including biases. A stable softmax turns scores into probabilities, and an action is sampled from that distribution.
Original generations
Recorded model conditions
The five primary conditions are Gemini Argon 4 Medium, Claude Sonnet 5.5, GPT-6 Original, GPT-6 Luna Extra High, and DeepSeek Original. Their original prompt copies, captured responses, parsed weight archives, and local metadata are preserved in the repository. The prompt is available here.
Provider names, model identifiers, one-shot status, tool settings, and reasoning effort are shown as recorded metadata. The independent audit found no provider-side attestations that authenticate those labels.
The Astra file is a reference controller. PPO is a trained reinforcement-learning baseline. Random-action and zero-weight policies are controls. DeepSeek Corrected is a later researcher intervention and must not be merged with original zero-shot generations.
Corrected local protocol
27,000 evaluation episodes
Nine conditions were evaluated for 3,000 episodes each, using seed groups 42, 100, and 200 with 1,000 episodes per group. The same base seeds and derived seed triplets were used across conditions. The evaluator creates separate environment and policy streams with numpy.random.SeedSequence(base_seed).spawn(2); MinAtar and categorical policy sampling each receive their own RandomState.
For each condition, the report includes mean, sample standard error, median, range, episode length, cutoff frequency, and selected/executed action counts. Paired comparisons use matched episode seeds, percentile bootstrap confidence intervals, two-sided sign-flip permutation tests, paired Cohen’s dz, and Holm correction over 36 comparisons. Nonsignificant comparisons are not equivalence evidence.
The corrected local evaluation is not the original paper’s sample: it uses 3,000 episodes rather than the reported 1,000, and uses a separated RNG protocol. Historical and corrected score differences combine that protocol change with different random draws.
Separate development experiment
Argon High — iterative development
The experiment evaluates the inline original assignments and two separate researcher-directed follow-up scripts, 3,000 matched episodes per version. The follow-up versions are interventions during development; they are not independent zero-shot generations and do not replace Gemini Argon 4 Medium in the five-condition primary set. The network has the same 600 → 32 → 32 → 6 architecture. The paired analysis reports small effect sizes; the nonsignificant Follow-up 1 vs Follow-up 2 result does not establish equivalence.
All 9,000 episodes ended by ball loss with no time-limit cutoffs. The original provider response and identity remain unauthenticated, and the repository's separate archived Gemini run has metadata that conflicts with the Phase 2 Argon 4 Medium label. The supplied Follow-up 2 verifier contains an impossible float64 probability assertion; a separate 7,280-state comparison agreed with its own oracle, but this is not a proof about all MinAtar states. The full report and raw episode files are linked from Results.
Independent check
Phase 3 verdict: Verified with limitations
The audit independently checked the Phase 2 repository state, protected artifact hashes, corrected CSV summaries, matched-seed calculations, selected replay traces, and RNG separation. The raw metrics reproduced from the episode CSVs.
- Model/provider identity and some generation settings remain recorded metadata without independent authentication.
- The GUI test failures remained unresolved: six failed and three errored during Tk startup, before the GUI assertions ran.
- One generation per model and one environment do not support broad capability or reliability claims.
- The browser arena is a new educational port and is not benchmark-equivalent unless its conformance checks pass.
See the Phase 2 report and registry in the research repository for source artifacts.
People and tools
Recorded contributions
The repository describes the work as a human-led research effort supported by AI coding and model-generation tools. It preserves the task prompt, captured model responses, parsed weights, evaluator, and later audit changes. The model outputs are the experimental objects; they are not trained during evaluation.
Project documents identify some model/tool roles, but they do not independently establish provider identity or give a verified, line-by-line attribution of who implemented each component. This site therefore reports contributions at the level supported by those records and does not claim that a researcher personally implemented or understood every technical component.
Limits of the evidence
What these results can and cannot show
The evidence concerns five fixed generations, one small architecture, one game, and one corrected local evaluation. It can describe how these particular archived networks performed under this protocol. It cannot establish model-wide capability, reliable repeatability across independent generations, or performance in other tasks.
The Astra policy is handcrafted/reference, PPO is trained, and random/zero-weight conditions are controls. DeepSeek Corrected is a post-hoc intervention. Keep each category distinct when interpreting the ranking.